
News brief · About 2 min read
Tibo separates 12-hour API caching from Codex and Work conversation continuity
His Day 16 post describes two caching scopes; neither should become a blanket promise of perpetual public API caching.
- Published here
- Source published
- Source checked
Original X post
Identity evidence () · Source published:
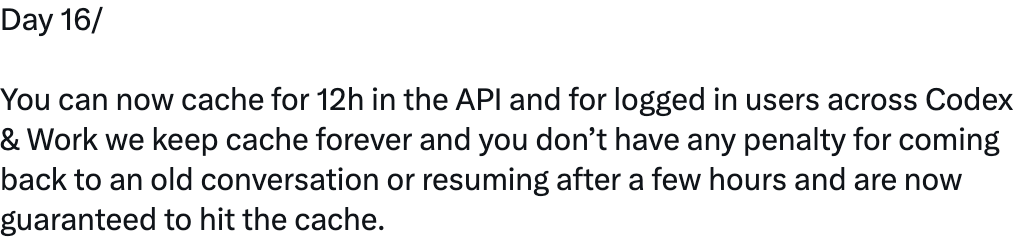
This is a partial screenshot of the original post’s body. The author, verified role and exact original publication time are stated in the source information; this image does not show the complete X page.
A reviewed screenshot of the public original post, shown as editorial evidence. Rights remain with the original rights holders; this does not imply a reuse licence.
Screenshot captured:
In his Day 16 post, Tibo says API users can now cache for 12 hours. He separately describes persistent caching for logged-in users across Codex and Work, including returns to older conversations or sessions resumed after several hours.
Listen to the news
Read this article aloud or keep listening to the news.
Preparing the reader…
Device voice
Speech is handled by your browser or device. AISubHub does not send the text to an audio API. Voice availability and playback with a locked screen vary by device.
Resuming may repeat a short phrase.
What the author said · editorial paraphrase
- For the logged-in product experience, he claims the cache is retained indefinitely and that resumed conversations are guaranteed a cache hit. Those are the author’s claims, not independently measured results.
- The 12-hour API option and the logged-in Codex and Work statement are distinct scopes; the latter must not be applied to every public API request.
AISubHub analysis
This distinction matters when planning context reuse: an API retention option and a product’s conversation-continuity behaviour are different interfaces, even when the announcement discusses them together.
Limits and availability
The post provides no complete model eligibility, exception list or token-rate table. We did not test cache hits, and this is not an independently verified SLA or a universal ChatGPT subscription quota increase.
Sources and evidence
Source published: · Source checked:
AI-assisted editorial articles checked against linked primary sources. Vendor claims are attributed; inclusion is not endorsement.